Data Engineering Services for Businesses That Need Reliable, Usable Data
When reports don’t align, pipelines fail, analysts spend hours cleaning files, or critical data sits across disconnected systems, the problem is rarely the dashboard itself. The underlying data infrastructure needs attention.
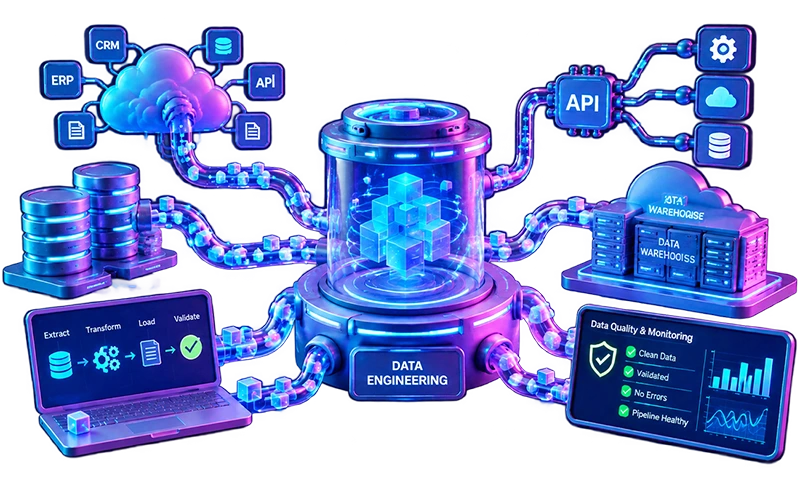
KernDev provides data engineering services for organizations that need data collected, integrated, processed, stored, validated, and delivered in a dependable way. Our engineers work across data pipelines, APIs, databases, warehouses, cloud platforms, and existing business systems so your teams can work with data they can actually use.
You get an engineering team that can assess the current environment, define the right architecture, build the required pipelines, test the data flow, and support the platform after deployment.
Your Data Problem May Be an Engineering Problem
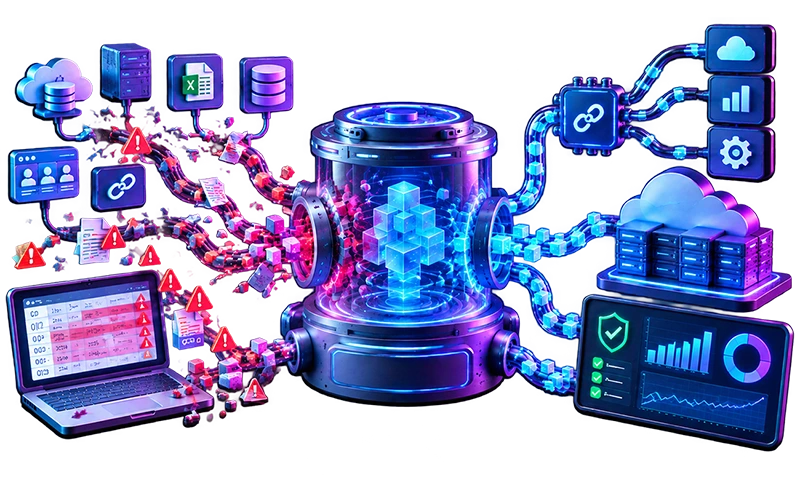
A business can have excellent analysts and still struggle to get reliable information.
You may be dealing with:
- Sales data coming from several systems with different formats
- Finance and operational reports producing different numbers
- Manual CSV or spreadsheet exports
- Customer records duplicated across platforms
- APIs that provide incomplete or inconsistent data
- Data pipelines that fail without clear visibility into the cause
- Legacy databases that were never designed for current reporting needs
- Delayed information reaching dashboards and internal applications
- Growing volumes of data putting pressure on existing infrastructure
- Developers spending too much time maintaining internal data processes
These problems create more than technical inconvenience. They consume employee time, delay decisions, make reporting harder to trust, and can leave teams working around the same technical limitations every week.
Our role is to identify where the data flow breaks down and address the underlying engineering problem. Through API development services, we can help businesses build more reliable connections between systems, improve how data moves across applications, and reduce inconsistencies between operational and reporting environments.
That may mean rebuilding an ingestion process, restructuring transformations, connecting systems via APIs, introducing a warehouse, improving data validation, or redesigning how information moves between operational applications.
The Industries We Serve
E-commerce & Freelance Marketplaces
Fintech & Financial Management
Healthcare and Wellness Solutions
Real Estate (Proptech)
Automotive and Mobility Technology
Digital Food Service Platforms
Educational Platforms
Game Design and Development
Sports and Mental Health
Banking & Finance
HRTech & Workforce Management
Logistics & Inventory
ERP (Enterprise Resource Planning)
CRM (Customer Relationship Management)
GovTech & Enterprise Administration
What We Actually Build?
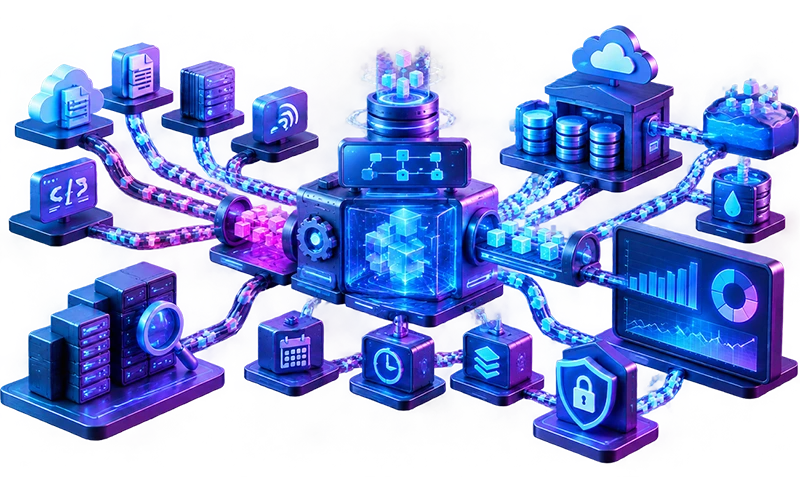
Data engineering services should not begin with a list of tools. They should begin by examining how your business creates, moves, stores, and uses information. When the underlying database architecture also needs to be built, modernized, or optimized, our database development services can provide the foundation for reliable data storage and access.
Our team can build and support the engineering layer behind:
- ETL and ELT pipelines
- Batch data processing
- Event-based data processing
- API-based data ingestion
- Database replication
- Data transformation and validation
- Data warehouses and analytical storage
- Data lakes and lakehouse environments
- Reporting and analytics data models
- Operational data stores
- Data migration processes
- Pipeline scheduling and orchestration
- Monitoring and failure handling
- Data access controls
- Documentation and data lineage
For organizations comparing a data engineering company based on technical depth rather than presentation alone, the important question is what happens after the engagement starts.
At KernDev, our engineers first understand the systems involved. We identify where information originates, how it currently moves, where it changes, where it becomes unreliable, and what downstream applications depend on it.
Only then do we decide what should be built or changed.
Stop Adding Fixes to a Data Architecture That Needs a Review
A common mistake is treating every data problem as an isolated pipeline issue.
When one pipeline fails, another script is added.
A report is missing information, so someone manually exports another spreadsheet.
Two systems disagree, so an analyst reconciles the numbers every week.
A database becomes difficult to query, so reporting is moved somewhere else without addressing the underlying structure.
Over time, the business ends up with more connections, more scripts, more dependencies, and fewer people who understand how everything fits together.
Our data engineering agency approach starts differently. We review the entire flow before recommending development work.
That assessment can cover:
- Source systems
- Databases
- APIs
- Data formats
- Existing pipelines
- Transformation rules
- Storage architecture
- Reporting requirements
- Access requirements
- Failure points
- Monitoring
- Existing technical debt
The objective is not to rebuild everything. It is to determine what actually needs to change and what can remain in place. For systems that require ongoing oversight after implementation, our IT support maintenance services can help keep applications, integrations, databases, and data workflows reliable as business requirements evolve.
Need Engineering Guidance Before You Build?
Not every organization needs a large data platform project.
Sometimes the immediate requirement is a well-defined pipeline. In other situations, the organization needs help deciding whether to use its existing database, introduce a warehouse, migrate workloads to the cloud, connect several applications, or restructure an unreliable ingestion process.
Our data engineering consulting services are designed for those decisions.
We can work with your technical and business teams to clarify:
- What data needs to move?
- Where it currently lives?
- How frequently it needs to move?
- Which systems depend on it?
- What quality rules apply?
- What storage model fits the workload?
- What should happen when a pipeline fails?
- Which parts should be automated?
- What can the existing architecture realistically support?
This matters because architecture decisions made too early, without understanding the business workflow, can create unnecessary development work later.
Our engineers focus on the actual requirement first, then determine the engineering approach.
When broader technology decisions are involved, Kerndev’s IT consulting services can help align the technical approach with your business requirements, existing systems, and long-term goals.
What Your Data Engineering Engagement Can Include?
We shape the engagement around the actual technical requirement rather than selling a fixed package.
Data Pipeline Development
We design ingestion and processing workflows around the systems that generate your data.
Depending on the requirement, this can involve scheduled processing, API ingestion, database replication, transformation logic, validation rules, and failure handling.
Data Integration
If your application, CRM, ERP, marketplace, internal database, or third-party platform needs to exchange information with another system, we examine the data structures and integration points before building the connection.
Our engineers can provide data integration engineering services where integration is part of a broader data platform or application initiative.
Warehouse and Analytical Data Architecture
If operational databases are being used for reporting workloads they were not designed to handle, we assess whether a separate analytical storage layer makes sense.
The work may involve data modeling, ingestion, transformation, historical storage, access patterns, and reporting requirements.
Data Quality and Validation
Moving data from one system to another does not automatically make it reliable.
We define checks around required fields, formats, duplicates, relationships, acceptable values, and processing failures where those controls are relevant to the project.
Cloud Data Engineering
KernDev works with AWS, Microsoft Azure, and Google Cloud to provide cloud and DevOps services according to project requirements. Where cloud infrastructure forms part of the requirement, our team considers the existing application, storage, processing workload, security requirements, deployment process, and operational responsibilities before recommending an architecture.
Our Process
Business and Data Assessment
We begin by understanding what the business needs from the data and how the existing environment currently works.
Our team reviews the relevant applications, databases, APIs, data sources, reporting requirements, processing rules, and known problems.
The goal is to separate the symptoms from the underlying engineering issue.
Architecture and Delivery Planning
Once the environment is understood, we define the proposed architecture and delivery scope.
This can include pipeline design, storage decisions, integration points, processing logic, data validation, access requirements, deployment considerations, and responsibilities between KernDev and your internal team.
Pipeline and Integration Development
Our engineers then build the agreed components, whether that involves new pipelines, integrations, transformations, migration processes, analytical storage, or changes to an existing data environment.
Development is handled within our broader software engineering organization, with project management supporting communication and delivery tracking.
Testing and Data Validation
A pipeline that runs without throwing an error can still produce incorrect data.
Our quality and assurance services process therefore considers both application behavior and the expected data outcomes. We test processing rules, integration behavior, failure conditions, data consistency, and relevant edge cases before release.
Deployment and Ongoing Support
After deployment, the work does not simply disappear from the engineering roadmap.
We can continue supporting the environment, investigating issues, working with your internal team, and handling further engineering requirements as the system develops.
What other Services Does Kerndev Provide?
Client Testimonials:
VP of Data & Analytics, HRTech & Workforce Management
Our workforce data was spread across multiple systems, making it difficult to get a reliable view of employee trends and operational metrics. Kerndev’s data engineering team built a scalable pipeline that brought everything together into a clean, centralized data environment. Reporting is now much faster, and our analytics team spends far less time fixing data issues.
Head of Technology, Logistics & Inventory
We needed a more reliable way to process data from warehouses, orders, shipments, and inventory systems. Their team redesigned our data pipelines and automated several manual processes, giving us much more consistent and timely information. It has made a noticeable difference in how quickly our operations team can identify inventory and fulfillment issues.
Director of Business Systems, Enterprise Resource Planning
Our ERP data had become increasingly complex as we added new business units and integrations. Kerndev helped us build a more structured and dependable data architecture while improving the flow of information between systems. We now have cleaner data, more reliable reporting, and a foundation that can support future growth without constantly rebuilding our infrastructure.
B2
B2
B2
B2
B2
B2
B3
B3
B3
B3
B3
B4
B4
B4
B4
B4
B5
B5
B5
B5
B5
Perks of Availing Kerndev Data Engineering Services
Built for Teams That Cannot Afford Unreliable Data Flows
We Do Not Start With Technology. We Start With Your Data Flow
How Our Data Engineering Services Supports Your Broader Technology Needs?
Our data engineering consulting company capability is useful when your organization already has developers, analysts, architects, or IT staff but needs additional engineering capacity or specialist experience.
We can work alongside an internal team rather than forcing the entire project into a separate delivery process.
That can include taking responsibility for a defined data pipeline, supporting an existing architecture, handling a migration, integrating external systems, or working with your developers on a larger application initiative. When those initiatives require broader engineering support, our software development services can help extend the application layer alongside the underlying data infrastructure.
For organizations evaluating data engineering service providers, this distinction matters.
You should know who is actually doing the work, who owns technical decisions, how progress is reported, and who remains available when something does not behave as expected after deployment.
KernDev has more than 500 software developers and 45 dedicated project managers across our broader engineering organization. That gives us the ability to bring the appropriate technical and delivery resources into a data engineering engagement rather than relying on a single individual to cover every responsibility.
This is one of the most important differences in how we approach data engineering solutions.
A technology choice can look appropriate on paper and still be wrong for the business if the team has not understood the source systems, data volume, processing frequency, reporting requirements, operational constraints, and people responsible for maintaining the platform.
Our engineers map the current environment first.
Then we identify:
What enters the system → where it is processed → where it is stored → who uses it → what can fail → how failures are detected → how the system will be maintained.
That gives the project a technical basis before development begins.
It also gives your stakeholders something concrete to evaluate before committing to a larger implementation.
Data engineering rarely operates in isolation, as applications, customer systems, security controls, and user-facing experiences all depend on reliable data flows.
Our custom application services can help connect business applications with the data pipelines and systems they depend on.
The design and UI services can support data-driven interfaces that make complex information easier for users to access and understand.
When customer data and business processes need to connect with your data environment, our CRM development services can support customized customer management solutions.
Our cybersecurity services can help protect data pipelines, integrations, storage environments, and other components of your data infrastructure.
For organizations validating a new product or idea, our MVP development services can help turn an initial concept into a functional solution for early testing and feedback.
Businesses can use our AI development services to build intelligent applications and integrate AI capabilities into existing data and software environments.
By considering these requirements together, our engineers can help reduce disconnected systems, duplicated data, and integration issues as your technology environment grows.
You Do Not Need to Commit to a Large Project Before Seeing How We Work
Choosing a data engineering partner is also a decision about communication, technical ownership, reporting, and day-to-day execution.
KernDev does not charge upfront. Clients can test our services for one month and then decide whether they want to continue working with us.
That gives your team an opportunity to experience how we communicate, how work is handled, how progress is reported, and how our engineers work with your existing people before making a longer commitment.
Have a data pipeline, integration, migration, or architecture problem to discuss? Talk with our engineering team about the current environment and the next practical step.